On-Device AI Inference and the Data Exposure It Eliminates
Keeping AI processing local prevents sensitive data from reaching vendor servers.
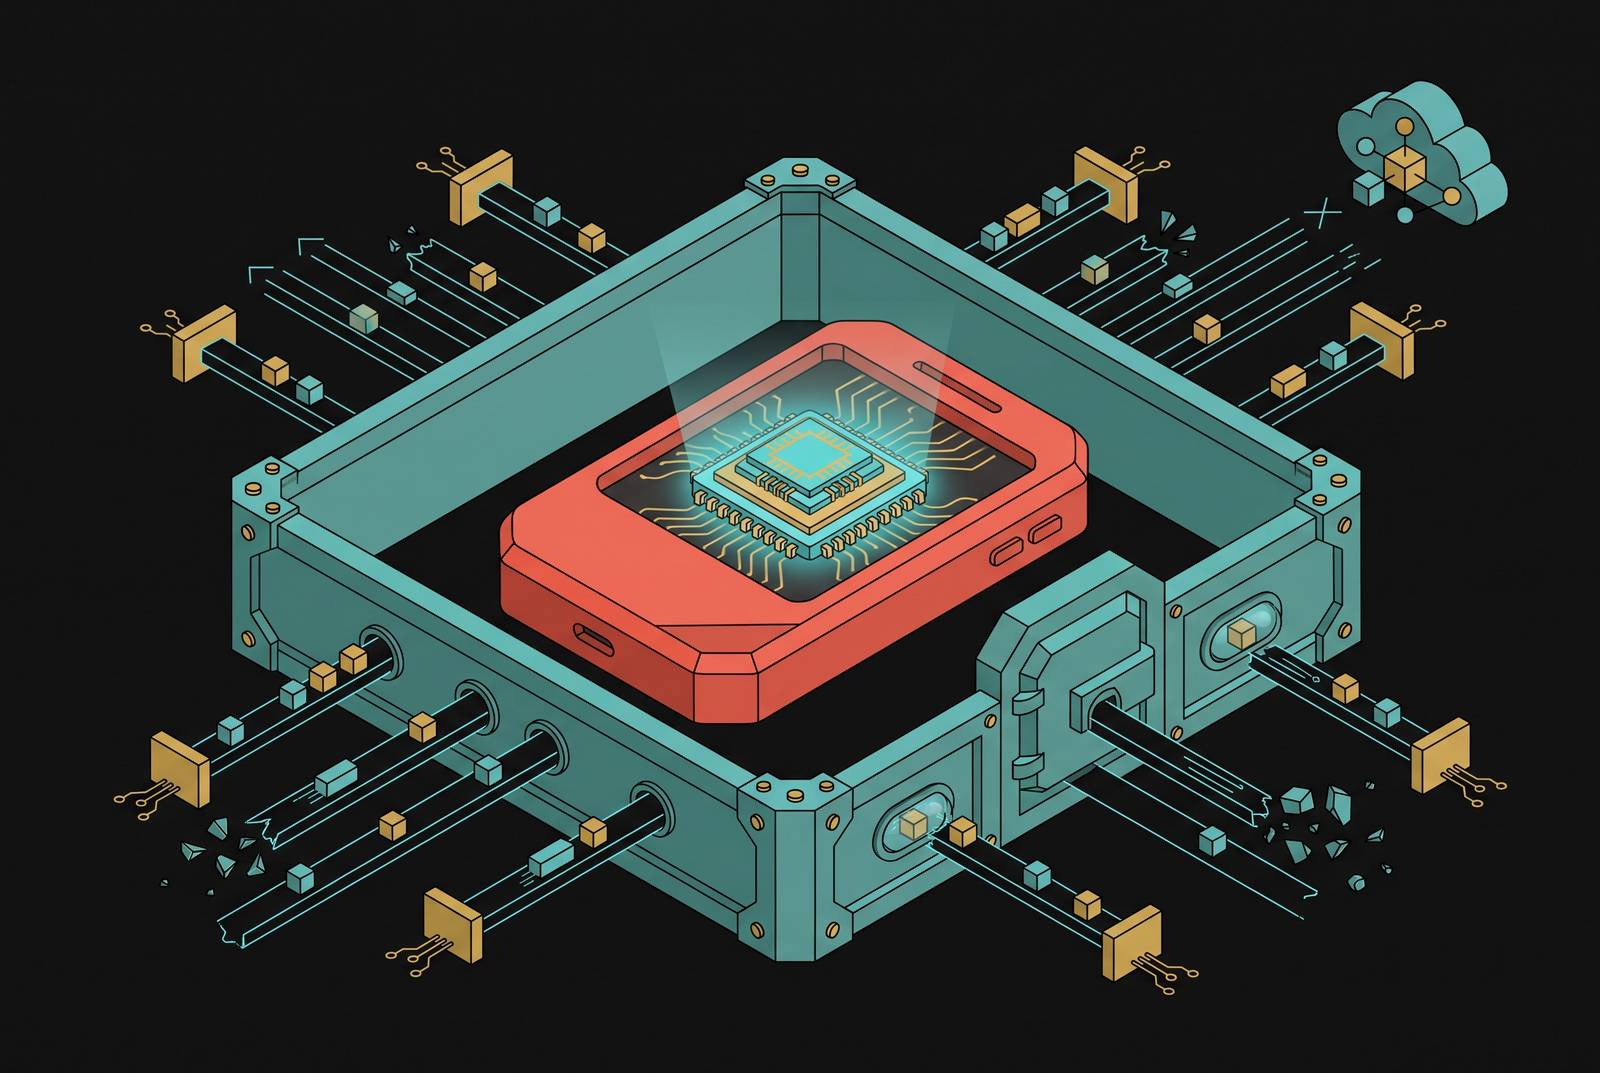
On-device AI inference eliminates exposure of prompts to vendor servers by keeping prompts and processing on the user’s device. For zero-trust AI architecture for enterprise, the decisive requirement is that the model runs locally and the application cannot transmit sensitive inputs or outputs. That protection removes dependence on vendor promises about handling those inputs, but it does not eliminate local security or privacy risks.
How cloud inference works and what crosses the network when it does
An employee pastes a contract excerpt into an AI tool and asks for a summary. It feels as routine as editing a document. Yet if the tool uses cloud inference, that text goes through servers the vendor controls before a response comes back. The same is true of a clinical note, financial document, confidential prompt, or attachment. The exposure begins with that transfer.
Once the content arrives, the enterprise lacks direct control over where it is processed, how long it is retained, or who can inspect it. Prompts may enter logs, debug traces, and caches, while attachments may be retained for “product improvement.” These are ordinary parts of service operation. A promise not to train models on prompts does not establish what happens in every intermediate system, and the customer cannot independently inspect infrastructure it never directly accesses.
How much context should an employee provide? More documents, message history, and fuller prompts can improve an answer, but they also widen the blast radius of a retention or access failure. The same information that makes the tool useful becomes part of the transfer. That tension is built into the workflow.
Why vendor commitments and contractual controls don't close the gap
A Data Processing Agreement can restrict what a vendor does with submitted content. It cannot prevent a transfer that the service requires. A no-training commitment addresses one downstream use, while leaving transit, server-side processing, abuse monitoring, and logging in place. The distinction is between limiting permitted behavior and removing the opportunity for access.
Stronger contractual arrangements still have real value. A privacy-first API provider can commit to no training, zero or minimal retention, a processor role under GDPR and CCPA/CPRA, and customer-selected data residency. Each narrows a different part of the exposure. Even with all these terms in place, the content has already entered another party’s systems. What happens if the enterprise’s requirement is that the provider never receives it?
That requirement exposes the limit of contractual controls. Data minimization, purpose limitation, and erasure obligations set rules for how data is handled, but with third-party inference, the transfer must first have a legal basis. It may require a Data Protection Impact Assessment and, for non-EU providers, an adequate transfer mechanism. No agreement can un-transfer a prompt that has crossed the network boundary.
How do you prevent an AI vendor from seeing internal prompts and data?
Running inference on the user’s device keeps the content from reaching the vendor, as long as the application cannot send it elsewhere. There is no prompt transmission to the vendor, no third-party storage of the inputs or outputs, and no server-side prompt log. A vendor retention policy has no sensitive content to govern.
The network restriction is the decisive condition here. A model that runs locally while its application transmits inputs through another feature does not meet it. By contrast, when local execution is paired with no network permission for that feature, sensitive content has no permitted outbound route. For medical images, financial documents, or biometric data, this means there is no external inference transfer and no server-side exposure from that transfer. It does not erase the device’s own attack surface.
Apple Intelligence illustrates both the principle and its boundary. Apple routes requests to a local model first, then uses Private Cloud Compute for harder tasks that require its cloud tier. Apple states that personal data in that tier is not stored or made accessible to Apple, and it has published server software images and opened a public bug bounty for independent verification. That is a separate architectural response to vendor access. It is not the same as eliminating transmission, because cloud processing still requires the request to leave the device.
The regulatory environment that has made cloud inference legally precarious for sensitive workloads
An organization that processes EU personal data through U.S.-based AI services must account for cross-border processing as well as whether prompts are used to train a model. As of 2026, over 75 countries have enacted some form of data localization or data sovereignty legislation.
The EU–U.S. Data Privacy Framework survived its first court challenge in September 2025, but a pending CJEU appeal and weaker oversight safeguards leave its future in doubt without making every transfer unlawful. A deployment that relies on systematic transfers therefore depends on a legal framework whose future is still in dispute. Financial services, healthcare, the public sector, and life sciences face this uncertainty while managing growing AI-induced data volumes and cross-border governance demands.
French CNIL published non-binding recommendations on January 5, 2026, on how to apply the GDPR when developing AI systems, including the use of encryption and data minimization. Those recommendations did not specifically target U.S.-based AI services or mandate supplementary measures beyond Standard Contractual Clauses. The distinction prevents overstating the regulatory signal. Still, most AI API processing requires the model to access plaintext, so encryption does not by itself answer who can access content during inference. Keeping processing where the data already lives avoids the need for a legal basis for an external transfer, while other legal obligations remain.
How the enterprise shift toward private and on-device inference is showing up in deployment decisions
Broadcom’s Private Cloud Outlook 2026 found that most enterprises are running or plan to run production AI inferencing on private cloud, while the use of public cloud for those workloads fell sharply from the year before. The report identified data protection, privacy, security, and control as leading new demands that AI places on enterprise IT. Organizations are making deployment decisions that change where processing happens so they have less work to do to govern data sent to external services.
Private cloud and on-device inference are not interchangeable. Both can keep processing within a chosen boundary, but a private cloud VPC is not the user’s device. A hospital deployment archetype makes the distinction concrete through clinical note summarization using a fine-tuned small language model in a private cloud VPC. It processes PHI internally, avoids the exposure created by public API submission, reduces physician workload, and preserves audit control.
A financial services archetype puts the boundary closer still, with loan application fraud detection running locally. Local processing avoids a cloud round-trip while retaining ownership of fraud detection logic and preventing indirect competitive benefit from submitted training data. The protected asset is not only personal information. It can also be the organization’s own decision logic. These archetypes illustrate why enterprises choose private execution, rather than proving that every such deployment achieves the same outcome.
What on-device inference actually requires and where it falls short
Compact on-device models can make more factual errors, handle complex multi-step reasoning less reliably, and struggle with broad world knowledge. That gap deserves a direct comparison with the privacy benefit. A sensitive workload is not automatically a workload that a small model can perform well enough.
Hardware further narrows what can run locally. Memory is limited, sustained inference consumes battery power, and devices vary significantly. A model that runs smoothly on a flagship device may be impractical on mid-range devices, wearables, or IoT hardware. Deployment must therefore account for the actual device population as well as the model’s performance on a favorable machine.
Getting marginal inference cost to near-zero at scale takes substantial work upfront to optimize the model, test it on each type of device, and integrate it. High-frequency, latency-sensitive workloads are better placed to recover that investment, but breakeven can take months. A task that runs rarely may never save enough to pay for that engineering work, even if it can run locally.
The trade-off is moving as tools and models improve. Meta’s ExecuTorch, ONNX Runtime Mobile, and React Native ExecuTorch serve different training ecosystems, platform targets, and runtime footprints. Computer vision models that are ready for production now run inference in sub-20ms on mid-range mobile chipsets. Liquid AI’s LFM2.5 is designed for on-device deployment, with an extended context window for local execution in regulated industries including healthcare and finance. These developments broaden the feasible workload range without erasing the capability gap across all tasks.
Why "on-device" doesn't automatically mean private and what the residual risks are
Where does the rest of the application send data? That question remains necessary even when the model makes no network request for inference. Cached inputs, telemetry, analytics events, crash logs, third-party SDKs, and local backups can create routes out of the device. Overly permissive retention can also leave sensitive content available locally after its useful life.
Google Chrome’s May 2026 Gemini Nano incident shows why teams need to check which software can access a local model. Chrome silently downloaded a roughly 4GB model without a clear consent prompt. Browser extensions with the 'languageModel' permission can reach a local model endpoint, while third-party scripts on enrolled or localhost origins may also access it under specific conditions. A local endpoint is still an access boundary. Moving the model closer to the user does not remove the need to control which software can invoke it.
A deeper risk concerns what the model can infer. Gartner VP Analyst Bart Willemsen describes a shift from data exposure to insight exposure, in which AI reconstructs deeply personal insights without breaching traditional data controls. Gartner predicts that by 2029, most privacy incidents will arise from AI-generated inferences. A model can still draw harmful conclusions locally when prompts stay on the device.
These are engineering problems. Explicit permissions, minimal telemetry, network isolation of the model endpoint, and browser-layer script visibility address the residual access surface. Without those controls, a local model can remain a privileged process with an inadequately guarded entrance.
How to decide where inference should run for a given workload
Is the central concern vendor access to confidential prompts, cross-border transfer of regulated records, or the privacy of insights generated from otherwise controlled data? Those are different problems. A zero-trust AI architecture for enterprise should make clear which access it blocks through technical restrictions and which protections still rely on what another party does.
On-device inference is the clear fit when acceptable model quality and hardware capacity coincide with a strong reason to avoid transmission. Such reasons include regulated data, offline operation, and latency-sensitive features such as live transcription, real-time camera processing, and gesture recognition. Field service, point-of-care, aviation, and rural connectivity can require the model to work offline. High-frequency inference can also justify the upfront engineering expense when recurring cloud charges would accumulate faster.
Cloud inference is still a good fit when a task needs broad world knowledge, complex multi-step reasoning, or a model too large for the device at hand. For one-off and low-frequency workloads, running locally may cost more than it saves. When content is non-sensitive, there is less concern about sending it, which also changes the balance. A cloud fallback, however, must be evaluated as a transfer path rather than treated as part of an entirely local guarantee.
For an on-device deployment, the minimum privacy requirements extend beyond choosing the runtime. They include task-scoped model permissions, minimal telemetry with audit visibility, an isolated model endpoint, no third-party SDK access to inputs or outputs, and a clear policy for cached content after the session ends. For a platform claiming that the vendor cannot access company queries, those architectural boundaries are the relevant evidence. The final choice follows from the workload’s requirements, choosing local execution when transmission is the unacceptable exposure and using cloud capability where its benefits justify a permitted transfer.